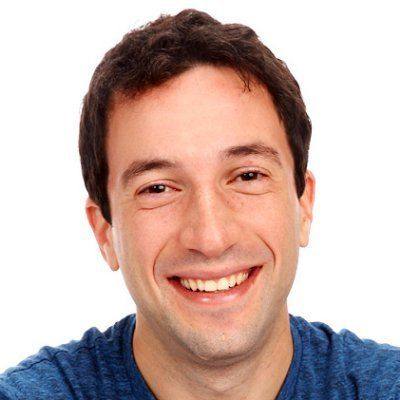
Co-founder and CEO of Snorkel AI, which he spun out of the Stanford AI Lab's Snorkel weak-supervision project. He has steered the company from enterprise labeling software to expert data, rubrics and evaluation environments sold to frontier labs, and is one of the most articulate public voices arguing the frontier is now 'expert agentic data'.
high confidenceSan Francisco Bay AreaAt Snorkel AI since 2019Updated 2026-09-19
Background
Harvard physics graduate (A.B. 2011) who worked in consulting analysing patent text before a CS PhD at Stanford (2019) under Chris Ré, where he started and led the open-source Snorkel project on programmatic labeling / 'data programming'. The observation that practitioners lacked labeled data, not better algorithms, became the thesis of 'data-centric AI'.
He co-founded Snorkel AI in 2019 and holds an (affiliate) assistant professorship at the University of Washington's Allen School.
What they run now
Runs the company's repositioning as a 'frontier AI data lab': Expert Data-as-a-Service (launched May 2025) for labs, Snorkel Evaluate, and a push into evaluation environments and public benchmarks (the $3M Open Benchmarks Grants). Publicly frames Snorkel's edge as combining expert networks with programmatic quality control and rubric design.
Career
2020 – present(Affiliate) Assistant Professor of CS, University of Washington, Paul G. Allen School — per UW new-faculty page and Snorkel bio
2019 – presentCo-founder & CEO, Snorkel AI
2019PhD student; led Snorkel open-source project, Stanford AI Lab
2019Stanford University, PhD, Computer Science — advisor Chris Ré
2011Harvard University, A.B., Physics
On the record
Expert agentic data · 2026-04
Argues the era of crowd micro-labeling is over; progress for the next decade-plus depends on domain experts building data for agentic tasks. source
Evaluation gap · 2026-04
Says agent capability is outrunning measurement; without rigorous evaluation you cannot improve or deploy agents safely. Frames evaluation along environment complexity, autonomy horizon and output complexity. source
Data vs environments · 2026-04
Rejects the split between 'data companies' and 'environment vendors'; task specs, rubrics and environments must be developed together. source
Enterprise AI · 2025-05
Enterprises need domain-specific data and expertise to get AI into production, not just bigger models. source
Data-centric AI · 2023-12
Long-standing position that better data, built with subject-matter experts, matters more than model tweaks. source
Recent posts
54 posts archived · most engaged first, then the latest
We are hiring for a ton of roles on our #Research team @SnorkelAI - if interested please reply/reach out!
As one of the first academic teams to focus on AI data development back at @StanfordAILab / @UW - we have long believed this is one of *the* most exciting areas to be as a researcher :)
Today - as a frontier data lab & partner to the world's leading AI labs and companies - we have more research vectors than we can possibly handle!
Come help us tackle problems in complex environment generation; long-horizon and non-stationary benchmarking; complex rubric and process reward design; data valuation and curriculum learning; core data quality control; human-in-the-loop system design; large scale RL systems; and more!!
Excited to see the GPT-5.6 launch using multiple recent Snorkel AI Open Benchmarks Grants-backed benchmarks:
- Agent's Last Exam
- Terminal-Bench 2.1
- OSWorld 2.0
Open benchmarks are critical guideposts for advancing the science of both AI model *and* data/env development!
All enterprises need some kind of specialized AI to be non-commodity in the AI era - and for that, they need a data flywheel. However: data flywheels are *not* built by just passively collecting user/agent interaction traces and then tuning on these. That is like telling a student to study only using their ungraded practice exams.
Most of the alpha and effort in AI today is getting *ground truth* - i.e. the grading keys/grades/answers to the practice exams - that enable tuning/RL to work. This is all about *high quality data* in the format of rubrics (grading keys), human evals (grades), and/or "gold" traces (correct answers).
Without this feedback signal, a data flywheel is fundamentally incomplete - and tuning on it will only reinforce inaccurate agent behavior.
Specialized AI that works is built with data flywheels that are continuously *developed* with the right annotation and data!
Also to be clear - these issues were *flagged by the @terminalbench team as PRs* (that's how Epoch identified them), and confirmed empirically to affect < 3% of the leaderboard rollouts, i.e. well within reported CIs.
This is not a "broken" benchmark - as is very directly implied by the Epoch report - it's a *continuous* benchmark where @alexgshaw@ryan_marten and team are earnestly advancing a compelling vision of open benchmarks that are continuously improved over time.
AI safety and alignment is more of a data + environment design problem than most realize!
Yes - there is great work to be done on inference time monitoring and controls, and better algorithmic (+ formal) approaches to alignment.
But the data models train on is the first contributor to whether they are safely aligned.
To a large degree: strong alignment comes from strong RL environment + dataset design:
- Are tasks, environments, rubrics, and evaluators robust to reward hacking?
- Are environments realistic and comprehensive in their coverage of real world settings?
- Are tasks realistic and diverse, balancing verifiability with realistic underspecification?
- Etc.
Just like discussions of raising well-aligned humans appropriately start w/ what they're taught at home... so too, AI safety & alignment discussions should pay more attention to the data & envs these models are trained on!
AI safety and alignment is more of a data + environment design problem than most realize!
Yes - there is great work to be done on inference time monitoring and controls, and better algorithmic (+ formal) approaches to alignment.
But the data models train on is the first contributor to whether they are safely aligned.
To a large degree: strong alignment comes from strong RL environment + dataset design:
- Are tasks, environments, rubrics, and evaluators robust to reward hacking?
- Are environments realistic and comprehensive in their coverage of real world settings?
- Are tasks realistic and diverse, balancing verifiability with realistic underspecification?
- Etc.
Just like discussions of raising well-aligned humans appropriately start w/ what they're taught at home... so too, AI safety & alignment discussions should pay more attention to the data & envs these models are trained on!
Braden Hancock — co-founder (left operating role 2024; now Laude Ventures/Institute, a Snorkel benchmark partner)
Todd Arfman (Addition) — lead investor, Series D
Who they amplify
Accounts whose posts Alex has reposted recently: Yacine Allaoua.
Why it matters here
Snorkel recruits 'visual, performing, or applied artists' in its expert community but its public focus is coding, law, finance and STEM agents, so creative/taste data is not a stated priority. Ratner's relevance is conceptual and competitive: he is defining the vocabulary (rubrics, environments, evaluation gaps) that labs use to buy expert data, and a taste-data specialist will be judged against that framing. Little evidence Snorkel is building a design-judgement practice.
How to reach
Active on X (@ajratner) and on podcasts; responds to substantive takes on evaluation and benchmarks. A concrete angle (speculative): pitch a rubric/benchmark for visual or design judgement to the Open Benchmarks Grants program (run by Vincent Sunn Chen) rather than cold-pitching Ratner directly.
What we could not establish
Current exact location not confirmed
Whether UW appointment is still active in 2026
No verified 2026 revenue or headcount figures; GetLatka $148M estimate is unverified
 Miju Labs